Holding Long Conversations in GPU Memory
Capacity engineering for a self-hosted, real-time guidance service on vLLM and Nemotron 3 Nano
Shawn Barnes · TensorSpace · October 2026
Abstract
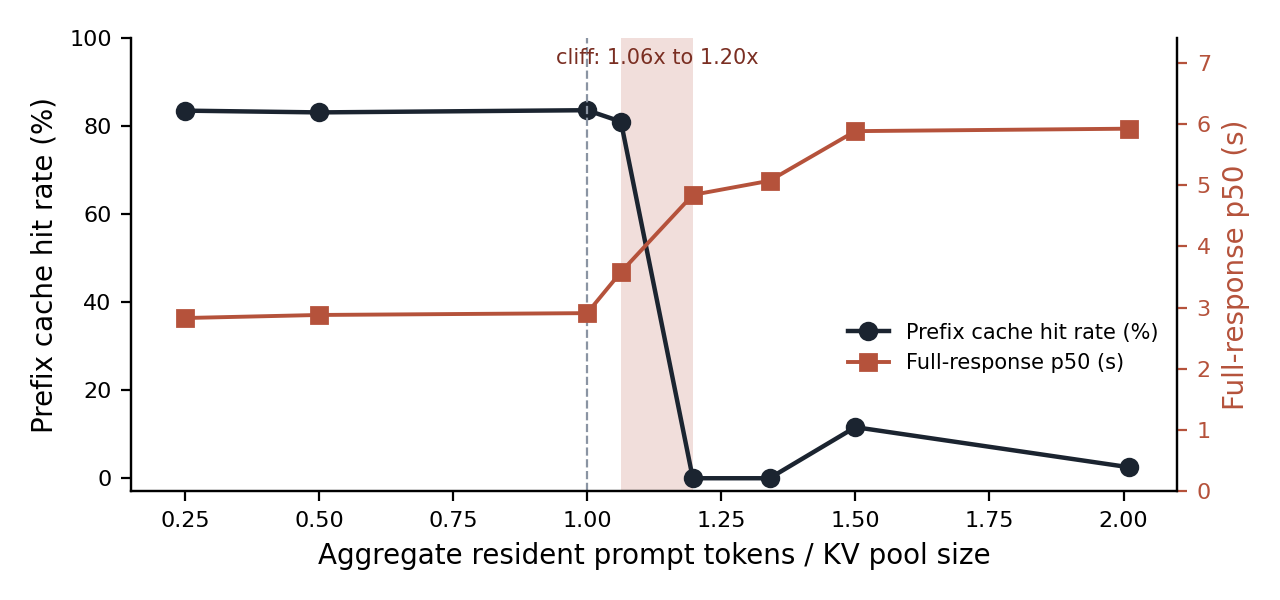
Advisory Guide is a customer support workflow tool that gives an agent short, grounded suggestions during a live conversation. Its serving cost is set by memory rather than compute: every session keeps a large, stable preparation prefix and a growing transcript resident on the GPU, while only a small fraction of sessions generate at any moment. Replacing a hybrid DeltaNet model with NVIDIA Nemotron 3 Nano 30B-A3B raised the reported KV pool on one H100 PCIe 80GB from 374,752 to 2,973,696 tokens at matched FP8 cache precision (7.9x). Prefix-cache reuse does not degrade gradually: hit rate held at about 83% up to the pool size and fell to exactly 0% between 1.06x and 1.20x of it. Admission was therefore expressed as a token budget at or below the pool, and a seven-hour soak served 69,312 requests across 200 resident sessions with zero errors and zero preemptions.
The cliff
Key results
| Measure | Result | Condition |
|---|---|---|
| Reported KV pool | 374,752 → 2,973,696 tokens (7.9x) | Matched FP8 KV, same H100 PCIe |
| Prefix cache hit rate | ~83% → 0.0% | Resident tokens 1.06x to 1.20x of pool |
| Rate ceiling | 3.0 req/s | Binds before residency at realistic cadence |
| Seven-hour soak | 69,312 requests, 0 errors, 0 preemptions | 200 sessions, 2.75 req/s |
| Output length effect | p90 23.95 s → 3.21 s | Production length instructions restored |